
01571: Pagelists do not sort correctly with UTF8
Description:
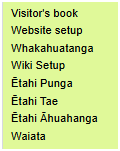
before
Pagelists do not sort correctly for UTF8.
This is a suggestion for an addition of a UTF8 sort function to xlpage-utf-8.php. along the lines of
function pmwiki_strcmpUTF8(?string $a, ?string $b): int {
# accent and case insensitive UTF8 pageline string comparison
# PmWiki allows NULL as a parameter
# returns the same values as strcmp()
    $a = $a ?? ""; # normalise null value
    $b = $b ?? ""; # normalise null value
    static $collator = NULL;
    if ($collator === NULL && \class_exists('Collator')) {
        # read system locale (e.g., "en_NZ.UTF-8")
        $sysLocale = \setlocale(LC_COLLATE, "0");
        # strip encoding suffixes so ICU can understand it
        $icuLocale = "";
        if (\is_string($sysLocale)) {
            $icuLocale = \preg_replace('/\..*$/', '', $sysLocale);
        }
        # try to create a Collator with the detected locale
        if ($icuLocale !== "" && $icuLocale !== "C") {
            $test = @new \Collator($icuLocale);
            if ($test !== NULL) {
                $collator = $test;
            }
        }
        # fallback locale if system locale is unusable
        if ($collator === NULL) {
            $collator = new \Collator('en_UK');
        }
        # PRIMARY strength = ignores both case and accents/diacritics
        $collator->setAttribute(\Collator::STRENGTH, \Collator::PRIMARY);
    }
    # Collator comparison
    if ($collator !== NULL) {
        return $collator->compare($a, $b);
    }
    # Fallback: decompose UTF-8 diacritics + case fold
    $aFold = \pmwiki_stripAccentsAndLowercase($a);
    $bFold = \pmwiki_stripAccentsAndLowercase($b);
    return \strcmp($aFold, $bFold);
} # end function pmwiki_strcmpUTF8
#
function pmwiki_stripAccentsAndLowercase(string $str): string {
    if (\class_exists('Normalizer')) {
        # Decompose characters into base letters + combining marks (NFD)
        $decomposed = \Normalizer::normalize($str, \Normalizer::FORM_D);
        if ($decomposed !== FALSE) {
            # Strip combining diacritical marks (\p{M})
            $tmp = \preg_replace('/\p{M}/u', '', $decomposed);
            if ($tmp !== FALSE) {
                $str = $tmp;
            }
        }
    } elseif (\function_exists('iconv')) {
        # Fallback diacritic removal
        $converted = @\iconv('UTF-8', 'ASCII//TRANSLIT//IGNORE', $str);
        if ($converted !== FALSE) {
            $str = $converted;
        }
    }
    return \function_exists('mb_strtolower') ? \mb_strtolower($str, 'UTF-8') : \strtolower($str);
} # end function pmwiki_stripAccentsAndLowercase
#
$PageListSortCmpFunction = 'pmwiki_strcmpUTF8';
On your screenshot, if we had to sort Māori words, "NG" and "WH" are considered separate single letters, so Whakahuatanga should come after Wiki setup. So you would set the locale to "mi_NZ", theoretically should work. Not sure why Waiata comes after the other W* - did you sort by title? --Petko
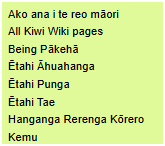
after
In config.php
$FmtPV['$TitleNoArticle'] = '\preg_replace("/^ *(?:The|An?) /i", "", (@$page["title"] ? $page["title"] : $AsSpacedFunction($name)), 1)'; // Use to order page lists without A,An,The and in the sidebar
(:pagelist fmt=#simpletitle order=$TitleNoArticle  group=Aotearoa,TeReoRangatira name={Site.Aotearoa$:ExcludePages} $:sidebar=-no -"(:redirect" :)
(:pagelist fmt=#simpletitle order=$TitleNoArticle  group=Songbook name=Waiata:)
"Waiata: shows up last because it is in a different group
Yes, strictly "wh" and "ng" are diagraphs, but, and practice varies, I'm happy to sort then as individual letters
There is no single universal rule for accent sorting across all languages, as alphabetical ordering is culturally defined. Different languages treat accented characters in contradictory ways:
- French / English: Accents are treated as secondary differences. Unaccented and accented forms are interleaved (e.g., cote, côte, coté, côté), with accents acting only as a tie-breaker.
- Swedish / Finnish: Accented characters like Å, Ä, Ö are distinct, standalone letters that appear at the very end of the alphabet after Z.
- Spanish: Traditional sorting treated Ñ as a separate letter after N, while accent marks on vowels (á, é, í, ó, ú) act only as tie-breakers.
- German: In standard dictionary sorting (DIN 5007-1), ä, ö, ü are treated like a, o, u, but in telephone directory sorting (DIN 5007-2), they are expanded to ae, oe, ue.
This is why we ought to redesign the pagelist sort functions to use Collator with a locale by default if it exists.
With the functions above, if the wiki does not have the Intl extension enabled, but uses the Cyrillic or Greek alphabet or CJK characters, the fallback may strip all characters, or order them by the Latin alphabetical order, not the Cyrillic or Greek order of their alphabets.
The code is also inefficient for large lists: it would be better and faster to normalise all values once, then sort the array of sorted values, rather than normalise the values every time every value is compared to all others. Since you already use a custom page variable, you could adapt this variable to strip the macrons (if it is used only for sorting), or add a new page variable for sorting.
Since you already use Cookbook:UnaccentUTF8, you can reuse that:
$FmtPV['$TitleNoArticle'] = '\UnaccentUTF8(\preg_replace("/^ *(?:The|An?) /i", "", ($page["title"] ?? $AsSpacedFunction($name))))';
Or more readable, possibly faster:
$FmtPV['$TitleNoArticle'] = 'myTitleNoArticlePCache';
function myTitleNoArticlePCache($name, $page) {
  global $AsSpacedFunction;
  $title = $page['title'] ?? $AsSpacedFunction($name);
  $title = preg_replace("/^(?:The|An?) +/i", "", trim($title));
  $title = UnaccentUTF8($title);
  return $title;
}
I admit for a generic case the efficiency should be improved in the core. --Petko